跟着这篇走完,你会在终端把 Meilisearch 的分面搜索与过滤跑通:声明可过滤属性、写 filter(搜索的过滤条件)组合与范围条件、拿回分面分布(facetDistribution)与数值统计(facetStats),再用 facet-search 做分面值自动补全。整个过程 7 步,每步都有一条命令能验证自己做对了没有。
动手前先交代下环境。localhost:7700 是 Meilisearch 的默认监听地址,master key 固定用 aSampleMasterKey(与第一篇一致),索引(Meilisearch 的独立文档集合,相当于一张数据表)固定用 books(本篇新建,不动第一篇的 movies),示例文档是 6 条虚构书籍;你要是换了端口、master key 或索引名,把示例值替换掉就行。这篇默认你已经装好并跑通了从零跑通 Meilisearch 本地搜索服务,还没跑起来先回去把服务起了再回来,安装、启动、异步任务轮询的套路全部复用第一篇。另外提醒一句:本文所有 filter 一律用官方字符串语法——显式 AND/OR/NOT 关键词加括号,不存在逗号或竖线操作符;范围过滤的写法是 price 10 TO 20(空格分隔,没有冒号)。
前置条件
| 项 | 要求 | 说明 |
|---|---|---|
| Meilisearch | v1.54.3 或更高 | 2026-10-01 发布的当前 stable,与第一篇一致;低于此版本 API 行为可能有差异 |
| 前置文章 | 已跑通 meilisearch-local-search |
本文复用其安装/启动/master key/异步任务轮询套路;没跑通先回去补 |
| curl | 任意版本 | 全文用 curl 调 REST API;jq 可选,用于美化输出 |
| 资源 | 2 GB 内存、1 GB 磁盘空闲 | 与第一篇相同,本篇 books 数据集极小,无额外负担 |
先跑这条,确认第一篇的服务还活着。
curl http://localhost:7700/health{"status":"available"}返回 {"status":"available"} 就满足条件。要是返回 curl: (7) Failed to connect to localhost port 7700,说明服务没起——回第一篇第一步用 meilisearch --master-key="aSampleMasterKey" 重新启动,再回来。
第一步:创建 books 索引(不动第一篇的 movies)
本篇换一套独立数据集 books,跟第一篇的 movies 索引互不干扰,后面几步就拿它当分面与过滤的靶子。索引走显式创建,直接把主键字段指定为 id——自动推断失败会报 index_primary_key_no_candidate_found,显式声明最稳。
curl -X POST http://localhost:7700/indexes \
  -H "Authorization: Bearer aSampleMasterKey" \
  -H "Content-Type: application/json" \
  -d '{"uid":"books","primaryKey":"id"}'
{
"taskUid": 0,
"indexUid": "books",
"status": "enqueued",
"type": "indexCreation"
}创建索引是异步任务,返回体里的 taskUid 就是这次任务的编号,后面靠它查进度。全新环境任务号从 0 开始;要是你的环境已经跑过其他任务,以实际返回的 taskUid 为准。
验证一下。
curl http://localhost:7700/tasks/0 -H "Authorization: Bearer aSampleMasterKey"{
"uid": 0,
"indexUid": "books",
"status": "succeeded",
"type": "indexCreation",
"details": { "primaryKey": "id" }
}返回里 status 是 succeeded、type 是 indexCreation,且 details.primaryKey 是 id,这一步就成了。万一任务 failed 且错误里带 primary_key,多半是文档结构让主键推断失败,排查入口见Meilisearch primary key 自动推断失败;返回 401 则是 auth 头没带或 master key 写错,见Meilisearch production 模式不设 master key 拒绝启动。
第二步:声明 filterableAttributes(filter 与 facets 的前提)
filter 和 facets(分面统计参数)有个共同前提:属性得先进 filterableAttributes 白名单。这个设置默认是空数组——啥都不声明的话,filter/facets 一律不工作。下面用子路由 PUT 一次声明五类字段,把后面会碰到的三种类型都覆盖掉:字符串数组(genres/language)、数值(price/rating),外加日期字符串(release_date)。
curl -X PUT http://localhost:7700/indexes/books/settings/filterable-attributes \
  -H "Authorization: Bearer aSampleMasterKey" \
  -H "Content-Type: application/json" \
  --data-binary '["genres","price","release_date","rating","language"]'
{
"taskUid": 1,
"indexUid": "books",
"status": "enqueued",
"type": "settingsUpdate"
}这一步有个容易忽略的点:设置更新也是异步任务(type 为 settingsUpdate),还会重索引该索引的全部数据,耗时跟数据量成正比。必须等任务 succeeded 之后,filter/facets 才真正可用——没等完就发带 filter 的搜索,会直接报 invalid_search_filter。
验证任务结果(taskUid 按实际返回为准):
curl http://localhost:7700/tasks/1 -H "Authorization: Bearer aSampleMasterKey"{
"uid": 1,
"indexUid": "books",
"status": "succeeded",
"type": "settingsUpdate"
}返回里 status 是 succeeded、type 是 settingsUpdate,说明属性声明生效了。等不到 succeeded 就发带 filter 的搜索,会报 Attribute "xx" is not filterable——要么是这一步没等完,要么属性名写错,排查路径见Meilisearch filter 报 Attribute is not filterable。
第三步:灌一批带分类/价格/日期字段的文档
往 books 索引写 6 条虚构书籍。字段类型是刻意设计的,别乱改——第五步、第六步的验证结果都依赖它们。genres 是字符串数组,用来测 = 匹配数组任一元素、IN 取并集;price/rating 是 JSON number,用来测 TO 范围与 facetStats 的 min/max;release_date 则是 YYYY-MM-DD 格式的字符串,测的是词典序范围比较。
curl -X POST http://localhost:7700/indexes/books/documents \
  -H "Authorization: Bearer aSampleMasterKey" \
  -H "Content-Type: application/json" \
  --data-binary '[
    {"id": 1, "title": "The Way of Kings", "genres": ["Fantasy", "Adventure"], "price": 19.9, "release_date": "2021-08-15", "rating": 4.8, "language": "English"},
    {"id": 2, "title": "Project Hail Mary", "genres": ["Science Fiction"], "price": 24.5, "release_date": "2022-05-01", "rating": 4.7, "language": "English"},
    {"id": 3, "title": "The Silent Patient", "genres": ["Thriller", "Mystery"], "price": 12.0, "release_date": "2019-02-19", "rating": 4.2, "language": "English"},
    {"id": 4, "title": "三体", "genres": ["Science Fiction"], "price": 29.0, "release_date": "2023-01-10", "rating": 4.9, "language": "Chinese"},
    {"id": 5, "title": "Dune", "genres": ["Science Fiction", "Adventure"], "price": 15.5, "release_date": "2020-10-01", "rating": 4.5, "language": "English"},
    {"id": 6, "title": "The Hobbit", "genres": ["Fantasy"], "price": 9.9, "release_date": "1997-06-26", "rating": 4.6, "language": "English"}
  ]'
{
"taskUid": 2,
"indexUid": "books",
"status": "enqueued",
"type": "documentAdditionOrUpdate"
}文档添加同样是异步任务,POST 返回的 taskUid 只表示入队,文档还没被索引。等对应任务 succeeded 再往下走。
确认数据到位。
curl -X GET http://localhost:7700/indexes/books/stats \
  -H "Authorization: Bearer aSampleMasterKey"
{
"numberOfDocuments": 6,
"isIndexing": false,
"fieldDistribution": {
"id": 6, "title": 6, "genres": 6, "price": 6,
"release_date": 6, "rating": 6, "language": 6
}
}返回里 numberOfDocuments 是 6、isIndexing 是 false,fieldDistribution 里能看到 id/title/genres/price/release_date/rating/language 六个字段,说明文档全部索引完。要是 numberOfDocuments 是 0 或 isIndexing 还是 true,多半是任务没等完,回第一篇把轮询套路捡起来,见Meilisearch 添加文档后立即搜索返回空结果。
第四步:filter 单条件与组合查询(AND / OR / 括号 / IN)
先分清请求 body 里的 q(查询词)和 filter(过滤条件),这两个参数是两条独立的检索通道,别混。
q 走的是全文相关性搜索:在 searchableAttributes(可搜索属性,默认是所有字段)里按词匹配,带容错和前缀匹配,结果按相关性打分排序——注意它不是子串匹配,搜 Fantas 不会命中 Fantasy。几种常见用法:
- 不传
q或传"":不做全文检索、返回全部文档,配合filter就是纯条件筛选(本步用的就是这种)。 - 多词:
"q": "dune fantasy",按词匹配后统一做相关性排序,同时命中全部词的文档排在前、命中不全的靠后。 q只决定命中和排序,不决定哪些字段能被过滤;要收窄可搜字段得去改searchableAttributes。
filter 走的是结构化条件筛选:只对 filterableAttributes 里登记过的字段做条件判断,文档要么符合要么被排除,不参与相关性打分。常用操作符和写法:
- 比较:
=、!=、>、<、>=、<=,以及范围值 TO 值(如price 10 TO 20)。 - 集合与存在:
IN取并集(如genres IN [Fantasy, Science Fiction])、EXISTS判断字段是否存在。 - 组合:
AND/OR/NOT加括号,AND优先级高于OR,跨条件组合务必显式加括号。
两者能叠加——同时传 q 和 filter 时,先用 filter 缩小文档集合,再对剩下这批用 q 排序。本步只关心筛选,所以下面的 q 一律传空字符串,意思是“不做全文检索,把 filter 命中的全部文档都给我”。参数细节见官方 Search API(POST) 与 Filter expression reference。
先跑单条件看看。genres 是数组,= 匹配的是数组中任一元素等于目标值的文档:
curl -X POST http://localhost:7700/indexes/books/search \
  -H "Authorization: Bearer aSampleMasterKey" \
  -H "Content-Type: application/json" \
  -d '{"q":"","filter":"genres = Fantasy"}'
{
"hits": [
{"id": 1, "title": "The Way of Kings", "genres": ["Fantasy", "Adventure"], "language": "English"},
{"id": 6, "title": "The Hobbit", "genres": ["Fantasy"], "language": "English"}
],
"estimatedTotalHits": 2
}hits(命中的文档列表)里应该是 id 1(The Way of Kings)和 id 6(The Hobbit)两条(上面返回值按可读性精简了其余字段)。单条件通了,再上组合。这里先记住一点:括号是强制的:
curl -X POST http://localhost:7700/indexes/books/search \
  -H "Authorization: Bearer aSampleMasterKey" \
  -H "Content-Type: application/json" \
  -d '{"q":"","filter":"(genres = Fantasy OR genres = Science Fiction) AND language = English"}'
{
"hits": [
{"id": 1, "title": "The Way of Kings", "language": "English"},
{"id": 2, "title": "Project Hail Mary", "language": "English"},
{"id": 5, "title": "Dune", "language": "English"},
{"id": 6, "title": "The Hobbit", "language": "English"}
],
"estimatedTotalHits": 4
}这条就是验证命令。先说为什么会这样:字符串形式的 filter 只有显式 AND/OR/NOT 关键词加括号这一种写法(没有逗号或竖线操作符),其中 AND 优先级高于 OR。把括号去掉,表达式会被解析成 genres = Fantasy OR (genres = Science Fiction AND language = English),language 约束只作用于 Science Fiction 那一支,结果自然不符预期。
组合规则不复杂:同一属性内多选值用 OR,跨属性约束用 AND,跨组的话括号别省。取并集还有等价写法 genres IN [Fantasy, Science Fiction];filter 也可以传数组形式(外层数组元素之间是 AND、内层是 OR,嵌套深度上限 2)。
期望输出:hits 里 4 条,id 1/2/5/6——每条都同时满足 genres 属于 {Fantasy, Science Fiction} 且 language 是 English;id 4 三体是 Chinese 被排除,id 3 两个条件都不满足也被排除。estimatedTotalHits(命中文档总数)应该也是 4。结果里要是混进了 language 不是 English 的文档,多半是 OR 把 AND 的约束吞了、括号没加,见Meilisearch filter 组合 AND/OR 优先级坑;要是报 Attribute "xx" is not filterable,回第二步,见Meilisearch filter 报 Attribute is not filterable。
第五步:范围过滤(数字 TO / 日期 / 字符串数组)
范围条件有三种形态,先分别看一眼写法:
# 数字范围:TO 等价于 >= AND <=,空格分隔、无冒号
curl -X POST http://localhost:7700/indexes/books/search \
  -H "Authorization: Bearer aSampleMasterKey" \
  -H "Content-Type: application/json" \
  -d '{"q":"","filter":"price 10 TO 20"}'

# 日期范围:按字符串词典序比较,格式必须统一(YYYY-MM-DD)
curl -X POST http://localhost:7700/indexes/books/search \
  -H "Authorization: Bearer aSampleMasterKey" \
  -H "Content-Type: application/json" \
  -d '{"q":"","filter":"release_date > 2020-01-01"}'

# 字符串数组并集:IN 写法(等价于 genres = Fantasy OR genres = Science Fiction)
curl -X POST http://localhost:7700/indexes/books/search \
  -H "Authorization: Bearer aSampleMasterKey" \
  -H "Content-Type: application/json" \
  -d '{"q":"","filter":"genres IN [Fantasy, Science Fiction]"}'
三条命令的返回(按可读性精简了文档字段):
# price 10 TO 20
{"hits":[{"id":1,"title":"The Way of Kings"},{"id":3,"title":"The Silent Patient"},{"id":5,"title":"Dune"}],"estimatedTotalHits":3}
# release_date > 2020-01-01
{"hits":[{"id":1,"title":"The Way of Kings"},{"id":2,"title":"Project Hail Mary"},{"id":4,"title":"三体"},{"id":5,"title":"Dune"}],"estimatedTotalHits":4}
# genres IN [Fantasy, Science Fiction]
{"hits":[{"id":1,"title":"The Way of Kings"},{"id":2,"title":"Project Hail Mary"},{"id":4,"title":"三体"},{"id":5,"title":"Dune"},{"id":6,"title":"The Hobbit"}],"estimatedTotalHits":5}
范围语法是 属性 值 TO 值,没有冒号,TO 等价于 >= AND <=,也可以拆成比较符组合。日期走的是字符串词典序,所以格式必须统一——混用 2020-1-1 和 2020-01-01 会比较出错。顺带提一句:比较型操作符(< > TO)计算资源密集,生产数据量大时可以考虑用 granular filterable attributes(对象数组形式)按需开启。
再验证一条组合,让三种条件同时生效:
curl -X POST http://localhost:7700/indexes/books/search \
  -H "Authorization: Bearer aSampleMasterKey" \
  -H "Content-Type: application/json" \
  -d '{"q":"","filter":"price >= 10 AND price <= 20 AND release_date > 2020-01-01"}'
{
"hits": [
{"id": 1, "title": "The Way of Kings", "price": 19.9, "release_date": "2021-08-15"},
{"id": 5, "title": "Dune", "price": 15.5, "release_date": "2020-10-01"}
],
"estimatedTotalHits": 2
}期望输出:hits 是 id 1 和 id 5 两条——价格落在 10~20 元区间且发布日期晚于 2020-01-01;id 2 价 24.5 超上限被排除,id 3/6 则是发布日期不满足被排除。要是数字范围完全不生效,先查字段类型:facetStats 与范围统计只认 JSON number,字符串形式的数字(如 "42")会被忽略,把字段转成 number 再试。
第六步:faceted search——拿 facetDistribution 与 facetStats
分面统计靠搜索请求里的 facets 参数触发,下面这条命令同时也是验证命令:
curl -X POST http://localhost:7700/indexes/books/search \
  -H "Authorization: Bearer aSampleMasterKey" \
  -H "Content-Type: application/json" \
  -d '{"q":"","facets":["genres","price","rating"]}'
{
"facetDistribution": {
"genres": {"Science Fiction": 3, "Fantasy": 2, "Adventure": 2, "Thriller": 1, "Mystery": 1}
},
"facetStats": {
"price": {"min": 9.9, "max": 29.0},
"rating": {"min": 4.2, "max": 4.9}
}
}带 facets 后,响应里会多出两个对象(上面只展示分面统计对象,hits 与 price/rating 分面分布省略)。facetDistribution 是每个分面属性 → 每个分面值 → 匹配文档数(比如 "genres": {"Fantasy": 2, ...});数值分面额外有 facetStats(比如 "price": {"min": 9.9, "max": 29.0}),前端画价格/评分区间滑杆就靠它。每个分面默认最多返回 100 个值(faceting.maxValuesPerFacet),要是 UI 只展示 Top 10/20,可以在 PATCH /settings/faceting 调小。
期望输出分三块对一下。facetDistribution.genres 里各分类计数应为 Science Fiction 3、Fantasy 2、Adventure 2、Thriller 1、Mystery 1;facetStats.price 是 min 9.9 / max 29.0;facetStats.rating 是 min 4.2 / max 4.9。
这里有个反直觉的坑要提前说:facets 里传入未声明为 filterable 的属性会被静默忽略、不报任何错——它不会出现在 facetDistribution 里。UI 上某个分面栏消失或为空,根因十有八九就是忘了声明,这跟 filter 参数直接报 invalid_search_filter 的行为截然不同,排查入口见Meilisearch facets 请求未声明属性导致 facetDistribution 为空。另外,facetStats 缺 min/max,多半是字段被存成了字符串数字,回第五步末尾的字段类型说明处理。
第七步(可选进阶):facet-search 分面值自动补全
这一步是给前端筛选器用的:输入分类关键字,下拉联想分面值。调 POST /indexes/{uid}/facet-search,这条命令同时也是验证命令:
curl -X POST http://localhost:7700/indexes/books/facet-search \
  -H "Authorization: Bearer aSampleMasterKey" \
  -H "Content-Type: application/json" \
--data-binary '{"facetName":"genres","facetQuery":"sci"}'{"facetHits":[{"value":"Science Fiction","count":3}],"facetQuery":"sci"}facetName(要搜索的分面属性名)必填,还必须在索引的 filterableAttributes 里(拼错或忘声明直接报错)。facetQuery(输入的分面关键字)只匹配分面值的第一个词:官方示例里搜 fic 能命中 Fiction,搜 Austen 匹配不到 Jane Austen——我们的数据集没有 Fiction,但 sci 能命中 Science Fiction。还有一条限制要记住:数值型分面值不可用 facet-search 搜索,需要可搜索就把数字转成字符串。
响应是 facetHits 数组(每项 value + count),默认按字典序升序;要是索引把设置 sortFacetValuesBy(分面值的排序方式)配成了 count,就按计数降序。
期望输出:返回值就是上面的样子(facetHits 一项、value 是 Science Fiction、count 是 3),看到这个就全通了。出错时按错误码对号入座:返回 400 invalid_facet_search_facet_name,是 facetName 拼错或没声明为 filterable,见Meilisearch facet-search 报 facetName 无效;invalid_facet_search_query 说明 facetQuery 传了非 string/null;facet_search_disabled 则是索引把 facetSearch 设置关掉了(默认是 true)。
核心概念
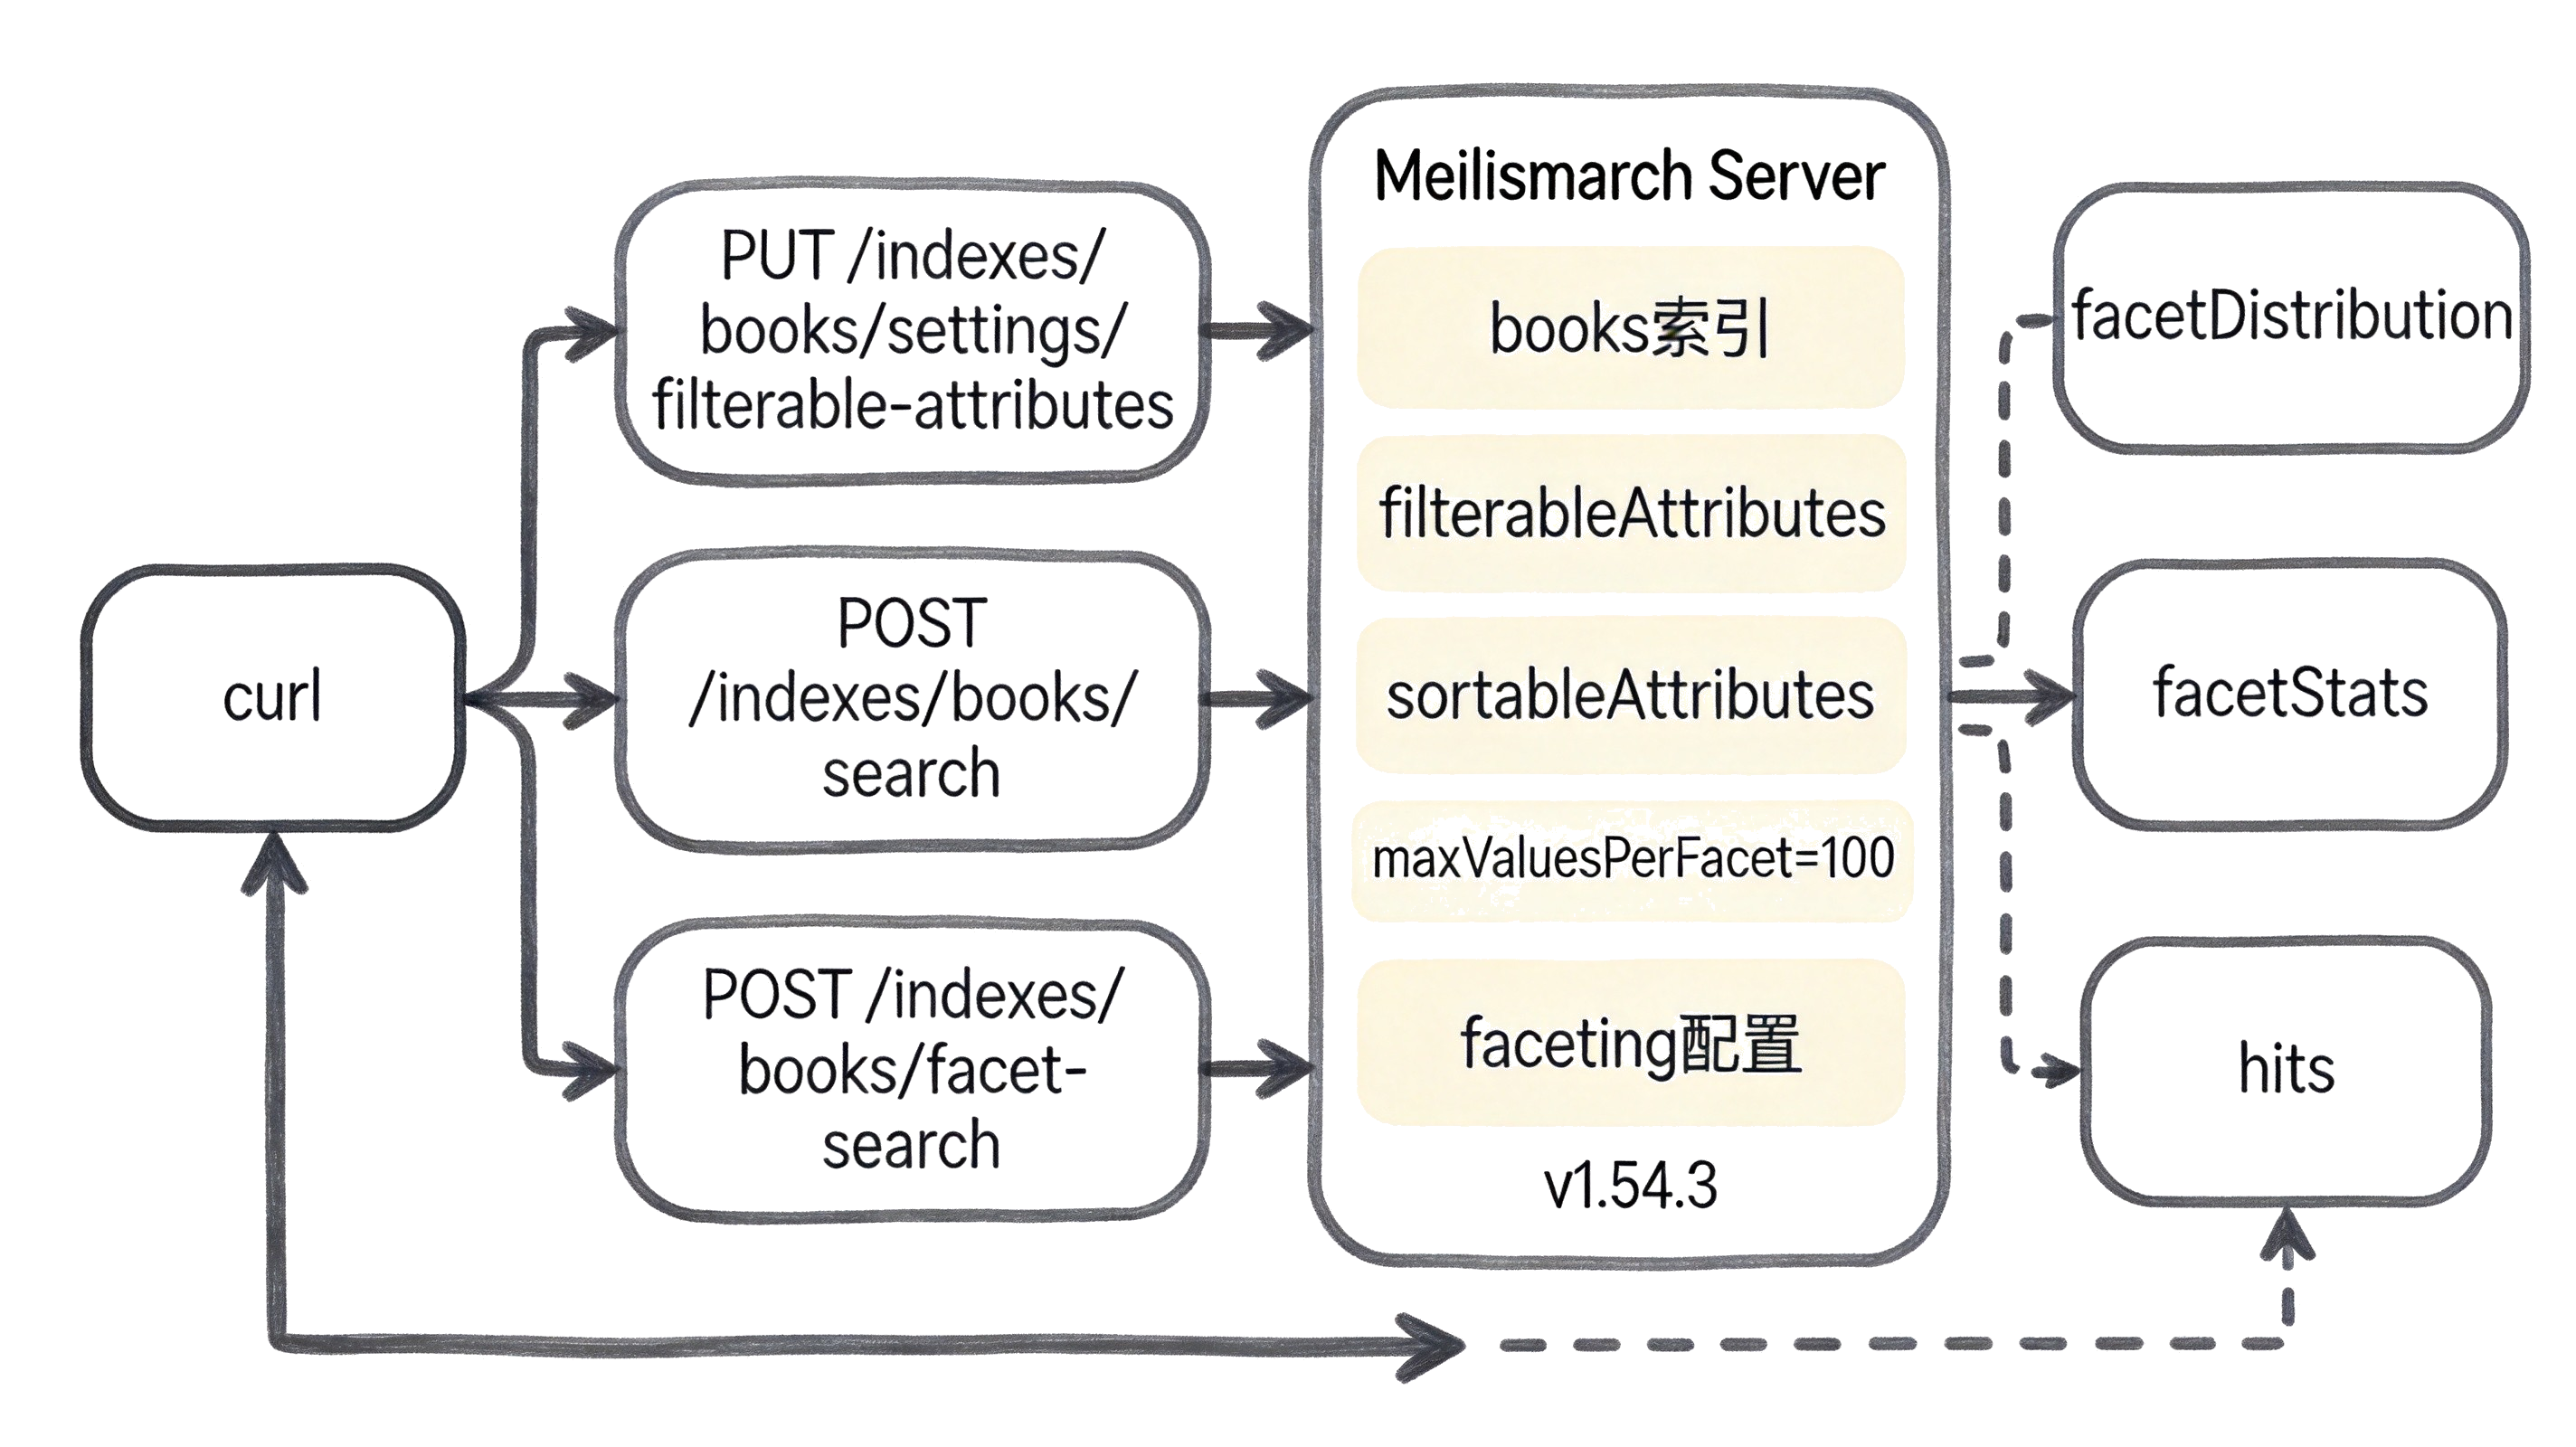
这张图是整条调用链路的走向,从左到右就是一次请求的完整路径。
| 概念 | 是什么 | 类比 |
|---|---|---|
| filterableAttributes | 声明后可被 filter/facets 使用的属性白名单,默认空数组;更新会重索引全部文档 | 像数据库里“可查询字段”白名单,没登记就查不了也分不了面 |
| filter 表达式 | 搜索的过滤条件,属性 操作符 值,操作符含 = != > < TO IN EXISTS,用 AND/OR/NOT + 括号组合;AND 优先级高于 OR |
像 SQL 的 WHERE 子句,属性得先登记(filterableAttributes)才能用 |
| q 与 filter 的区别 | q 是在 searchableAttributes(默认所有字段)里按词做全文检索,带容错和前缀匹配、按相关性排序(非子串匹配);filter 是对 filterableAttributes 做结构化筛选(命中/排除,不排序)。可叠加:filter 先缩小集合,q 再排序 |
像电商搜索:q 是搜索框里输的关键词,模糊匹配按相关度排;filter 是左侧筛选器,点分类/价格区间精确过滤 |
| facetDistribution | 分面分布统计:每个分面属性 → 每个分面值 → 匹配文档数,由 facets 参数触发 |
像电商左侧分类计数,每个分类下面挂着有多少件商品 |
| facetStats | 数值分面的 min/max 统计,只统计 JSON number 类型的字段 | 像价格滑杆的两端刻度,前端拿它画区间筛选器 |
| facet-search | POST /indexes/{uid}/facet-search,分面值的自动补全/下拉搜索,facetName 必须在 filterableAttributes |
像搜索框的联想下拉,输入 “fic” 出 “Fiction” 及计数 |
| sortableAttributes | 声明后可被 sort 使用的属性白名单,与 filterableAttributes 相互独立;一个字段可同时进两个列表 | 像 SQL 的 ORDER BY 字段白名单,filter 和 sort 各管各的授权 |
常见问题
facetDistribution 里某个分面缺失/为空,且服务端没有任何报错
现象:搜索请求带了 facets 参数,响应里 facetDistribution 缺了某个属性,或整个为空;Meilisearch 不报 4xx。
原因:facets 里传入的属性没有加入 filterableAttributes,Meilisearch 对分面属性静默忽略(与 filter 报 invalid_search_filter 截然不同),UI 上表现为分面栏消失或为空。
filter 组合结果不符预期,OR 把 AND 的约束“吞”掉了
现象:genres = Fantasy OR genres = Science Fiction AND language = English 返回的结果里混入了 language 不是 English 的文档。
原因:AND 优先级高于 OR,去掉括号的表达式被解析为 genres = Fantasy OR (genres = Science Fiction AND language = English);跨条件组合必须显式加括号。
invalid_search_sort:filter 正常,一加 sort 就报错
现象:filter 搜索返回正常,往 body 里加 "sort":["price:desc"] 后返回 400,错误码 invalid_search_sort。
原因:sort 用到的属性未在 sortableAttributes 里声明——filterable 与 sortable 是两套独立白名单,一个字段可同时出现在两个列表(filterableAttributes 与 sortableAttributes 都含 price 才能做 filter+sort 组合)。
invalid_facet_search_facet_name
现象:POST /indexes/books/facet-search 返回 400,错误码 invalid_facet_search_facet_name。
原因:facetName 不在该索引的 filterableAttributes 列表中(属性名拼错,或忘了声明);facet-search 的前置条件是分面属性必须可过滤。